contentDB
contentDB stores customer conversations, research, and content in one place so you can query it through MCP in Claude or ChatGPT while you research, write, or update an article.
How it works
contentDB is a workspace database where you can add your company’s high-value content from URLs or pasted text, including podcasts, transcripts, SME-led articles, ebooks, reports, surveys, LinkedIn posts, Reddit threads, and sales call transcripts. You can then search that material in the contentDB web app or query it from connected AI clients through MCP while writing or doing research.
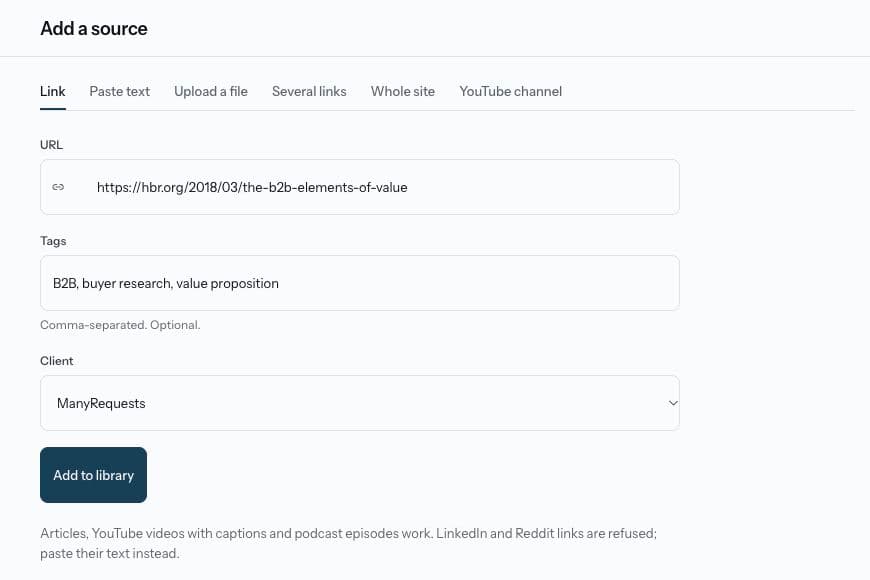
For LinkedIn posts and Reddit threads, paste the text instead of adding the URL.
Bring sources into one searchable system
Add links or pasted text, tag the right client, and make that source available for retrieval across the workspace.
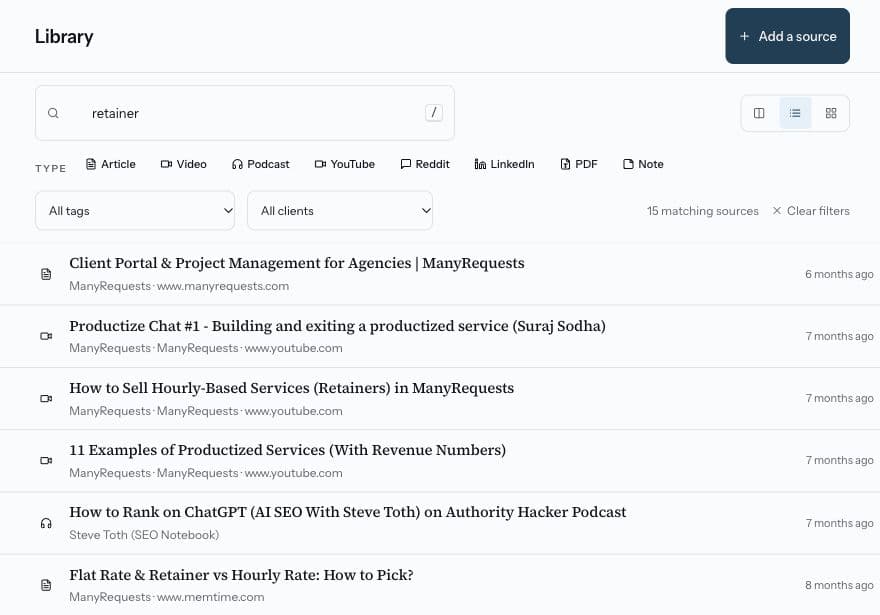
Search with quote context
Find exact moments, surrounding context, and client-tagged material instead of isolated snippets.
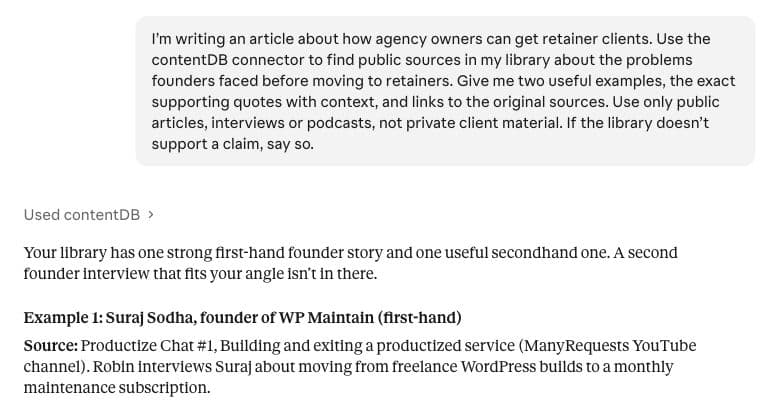
Turn that stored research into structured, source-grounded answers you can write from
I’m writing an article about how agency owners can get retainer clients. Use the contentDB connector to find public sources in my library about the problems founders faced before moving to retainers. Give me two useful examples, the exact supporting quotes with context, and links to the original sources. Use only public articles, interviews or podcasts, not private client material. If the library doesn’t support a claim, say so.
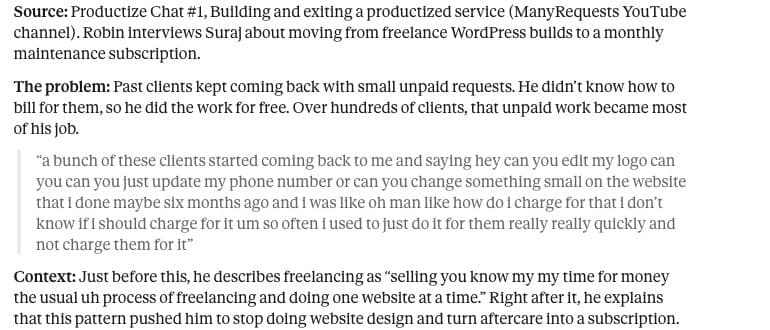
Claude gives a response from your database first, which helps keep the answer grounded. You can check the source and surrounding context before using it.
Problem it solves
When writing for clients or your company, useful context is usually scattered across many links, docs, calls, and transcripts. You’d have to spend time on Google searches, interview SMEs, or comb through existing podcasts and reports to find relevant material.
If you rely on Google search or generic AI output, the writing often becomes weak or repetitive. contentDB keeps all your context in one place so you can pull relevant quotes, supporting detail, and customer wording quickly via Claude or ChatGPT’s MCP to improve the credibility of your work.
Who it’s for
Content strategists, B2B SaaS marketers, writers in general, and agencies with multiple clients.
My role
I built it end-to-end: product direction, UX, data model, ingestion flows, transcript processing, pain-point extraction, semantic retrieval, MCP integrations, workspace access controls, and deployment setup.
Key features
- Add content from URLs, pasted text, or uploaded files, including articles, YouTube videos, podcasts, transcripts, and reports. Paste the text for LinkedIn posts and Reddit threads.
- Store customer conversations and transcripts in a structured format with segments, timestamps, and speaker metadata when available.
- Extract pain points and retrieve quote context before and after the match instead of isolated snippets.
- Search your sources and read passages in context from the web app.
- Use the same workspace context inside connected AI tools through MCP.
- Filter by client inside one workspace so you can retrieve material for the correct account.
What makes it different
- Manage and search your sources in the web app, and query the same material inside external AI tools through MCP.
- Retrieve contextual quotes from your database to support the answers you write from.
- Built for agency workflows where multiple clients share one workspace and research needs to stay organised by client.
Stack
Next.js · Node.js / Express · Supabase (Postgres/Auth) · OpenAI (embeddings + extraction) · MCP SDK · Railway
Why it matters
It makes writing workflows faster and more specific. Instead of starting from generic AI output, I can pull real context from a client’s content and customer language from shared calls, then use that material to produce stronger, more credible content.
Use contentDB
Use the web app to add and search your sources, then connect contentDB to your AI tools for research and writing.